STOP: Structured On-Policy Pruning of Long-Form Reasoning in Low-Data Regimes
Structured pruning of self-distilled reasoning traces reduces token use while largely preserving accuracy in low-data fine-tuning.
•
1 min read
Read more
Structured pruning of self-distilled reasoning traces reduces token use while largely preserving accuracy in low-data fine-tuning.

A benchmark and analysis of when tool-using LLM agents should stop and abstain rather than continue acting.
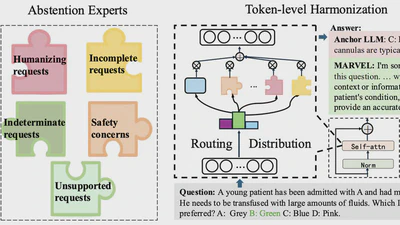
A modular abstention framework for reliable expert LLMs that enables selective abstention from uncertain questions.
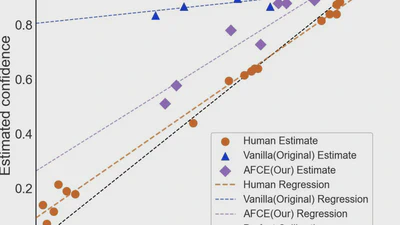
Exploring psychological insights to address overconfidence in LLMs by comparing with human confidence patterns.
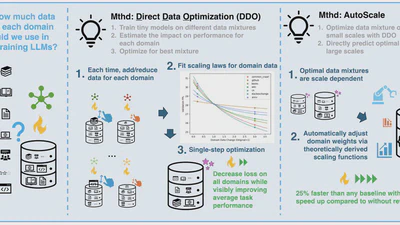
Automatic prediction of compute-optimal data composition for efficient LLM training.

A comprehensive survey of abstention mechanisms in large language models, covering theory, implementation, and evaluation.
Behavioral analysis and mitigation strategies for overconfidence in large language models.
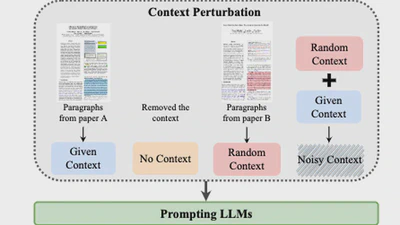
Characterizing LLM abstention behavior in science QA with context perturbations.