STOP: Structured On-Policy Pruning of Long-Form Reasoning in Low-Data Regimes
Structured pruning of self-distilled reasoning traces reduces token use while largely preserving accuracy in low-data fine-tuning.
•
1 min read
Read more
Structured pruning of self-distilled reasoning traces reduces token use while largely preserving accuracy in low-data fine-tuning.
Evaluation suite for diverse multitask multimodal generation with large multimodal models.

Reinforcement learning for agentic VQA that balances clarification and answering under underspecified context.
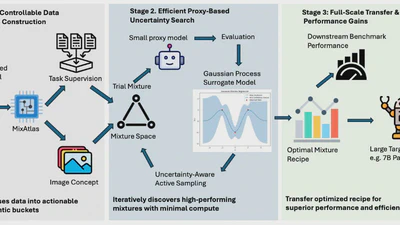
Uncertainty-aware data mixture optimization for multimodal LLM midtraining via interpretable domain decomposition.
Benchmarking dark pattern susceptibility of computer-use agents in realistic UI environments.
Context-driven clarification strategies for ambiguous VQA in a reasoning-focused NeurIPS workshop.
Benchmarking LVLM robustness to spurious correlations and studying generalization beyond the SpuriVerse.
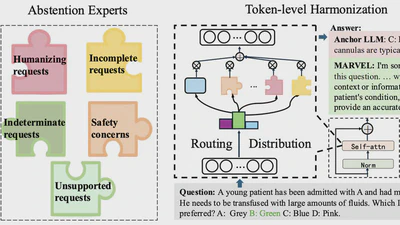
A modular abstention framework for reliable expert LLMs that enables selective abstention from uncertain questions.
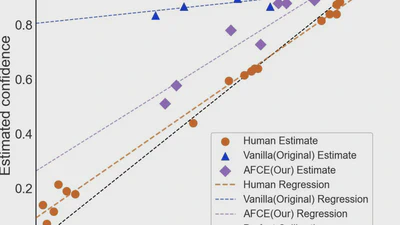
Exploring psychological insights to address overconfidence in LLMs by comparing with human confidence patterns.
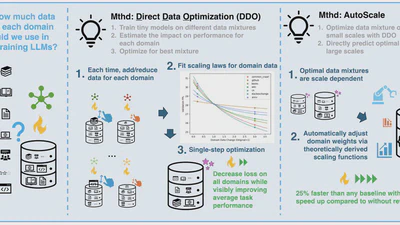
Automatic prediction of compute-optimal data composition for efficient LLM training.